GLM 5.3 Review: Why It Beat 128GB of Local AI at Running My Agents
I spent months trying to run my personal agents on local models on a 128GB Mac Studio. I switched to GLM 5.3 and everything they failed at worked the same day. Here's what it runs for me now.
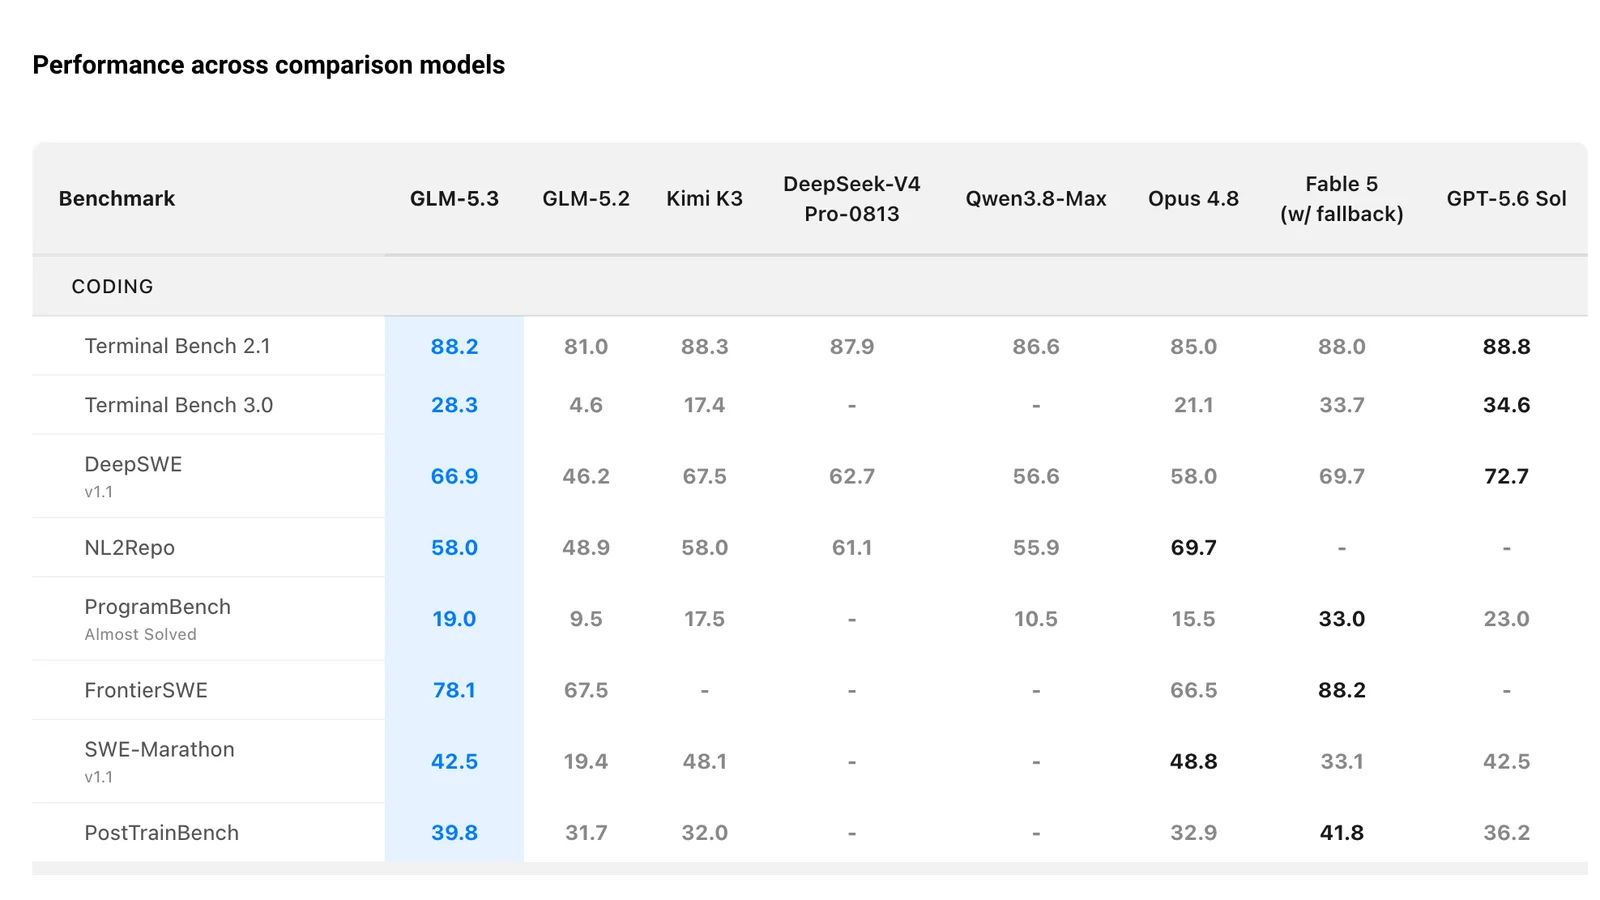 Z.ai's own coding benchmarks for GLM 5.3, from the launch post. My real test was whether my agents stopped lying to me.
I spent months trying to get my personal agents running on local models. Almost every session ended with me close to tearing my head off. So I gave up, begrudgingly, and switched to GLM 5.3. Every task I'd been fighting local models on worked the same day.
This GLM 5.3 review covers that switch and what the model runs for me now. It powers my Hermes agent, which handles a real chunk of my business. It powers Openclaw, which has been running my LinkedIn. And the GLM family built this website, starting back at GLM 5.
I gave local models a real shot
I had plenty of hardware for this. I run a Mac Studio with an M5 Max and 128GB of memory, which is a lot of machine for local AI.
I tried three runtimes: Ollama, LM Studio and oMLX. oMLX was the fastest of the three. But a faster runtime still runs the same model, and the models were the problem.
I spent most of my time with two of them. Qwen 3.8 Flash Next, and Nemotron Super VL running in NVIDIA's NVFP4 format.
I've made the case for local AI before, in why I run some AI locally and some in the cloud. Agents were where that case fell apart for me.
Where Qwen and Nemotron broke down
Both models made things up, then defended the wrong answer with total confidence. For an agent, that's the worst way to fail. An agent that lies about its own setup sends you hunting for problems that don't exist.
The email agent is the one that still bugs me. I wanted it to read my inbox and auto-respond to requests that didn't meet a certain threshold. The Gmail MCP server was connected. Everything was set up properly. The model kept insisting it had no access to my email. It absolutely did.
Then I connected that same Gmail server to a frontier model, and it got the whole job done right away. My setup had been fine the entire time.
My Pocket transcripts went the same way. I record meetings with Pocket, and I wanted every transcript backed up into my marketing brain so my other agents could use them. The local agent told me that was set up. When I checked, it wasn't.
The bigger pattern was orchestration. I'd say something like "build me this automation." A good agent turns that into a list of problems, then a list of changes, then hands the pieces to the right models. Qwen and Nemotron failed at that every single time. Coding automations fell apart the same way.
Local image generation was a bust too. I have a Telegram thread of failed images to prove it.
GLM 5.3 fixed it the same day
I moved my Hermes agent to GLM 5.3 expecting another letdown. Hermes Agent is the open-source agent from Nous Research, and it runs most of my business automations. By the end of that day, every task I'd been stuck on with local models was working.
The Pocket pipeline was the cleanest example. I had Claude and GLM 5.3 audit everything the local agent said it had built. They found the gaps, fixed them and ported the transcripts over perfectly.
That's the difference I care about most. When GLM 5.3 says something is done, it's done.
What does GLM 5.3 run for me every day?
GLM 5.3 runs the agents that handle the repetitive side of my business. Hermes triages my sales inquiries, audits my ad accounts and keeps my meeting transcripts in one place. Openclaw has run my LinkedIn on it, with me approving posts along the way. Here's the full list:
- Sales inquiries. Hermes manages a lot of my first-touch sales inquiries. When one needs me, GLM 5.3 sends me a notification.
- Ad audits. Hermes goes into my different ads setups, audits them and suggests changes. I decide what gets applied.
- Meeting transcripts. The Pocket backup the local model faked now actually runs. Transcripts land in my marketing brain, where all my agents can use them.
- LinkedIn. Openclaw reads the news, drafts a post, publishes it and replies to comments. I usually approve each post before it goes out. My local agents couldn't get through that loop at all.
- Instagram. I get automated notifications for Instagram comments, since I keep the app's own notifications turned off.
That's about it. I don't automate much else anymore. Someone once asked if I let Claude run my marketing 24/7, and I said no way in hell. GLM 5.3 lives by the same rule.
GLM has been building my websites since GLM 5
GLM 5 built the first version of prestonvawdrey.com. GLM models also did a huge share of the work on Draftly. That was insanely valuable for a side project with no revenue to justify Claude-level spend. I covered that build in my GLM 5.2 review.
Today GLM 5.3 is my go-to whenever something goes wrong with Claude or Anthropic. It handles anything I'd throw at Claude. That's saying something, because ChatGPT can't always do that for me.
What actually changed in GLM 5.3?
GLM 5.3 is a post-training upgrade on the GLM 5.2 base model, released by Z.ai on August 14, 2026. It keeps the 1M token context window, with up to 128K tokens of output. If you're on the GLM Coding Plan, requests for 5.2 now route to 5.3 automatically. Z.ai's biggest reported gains are in agentic coding.
According to Z.ai's GLM 5.3 launch post, Terminal-Bench 3.0 jumped from 4.6 to 28.3 and DeepSWE went from 46.2 to 66.9. Those are Z.ai's own numbers. They line up with what I saw, since agent work is exactly where my local models died.
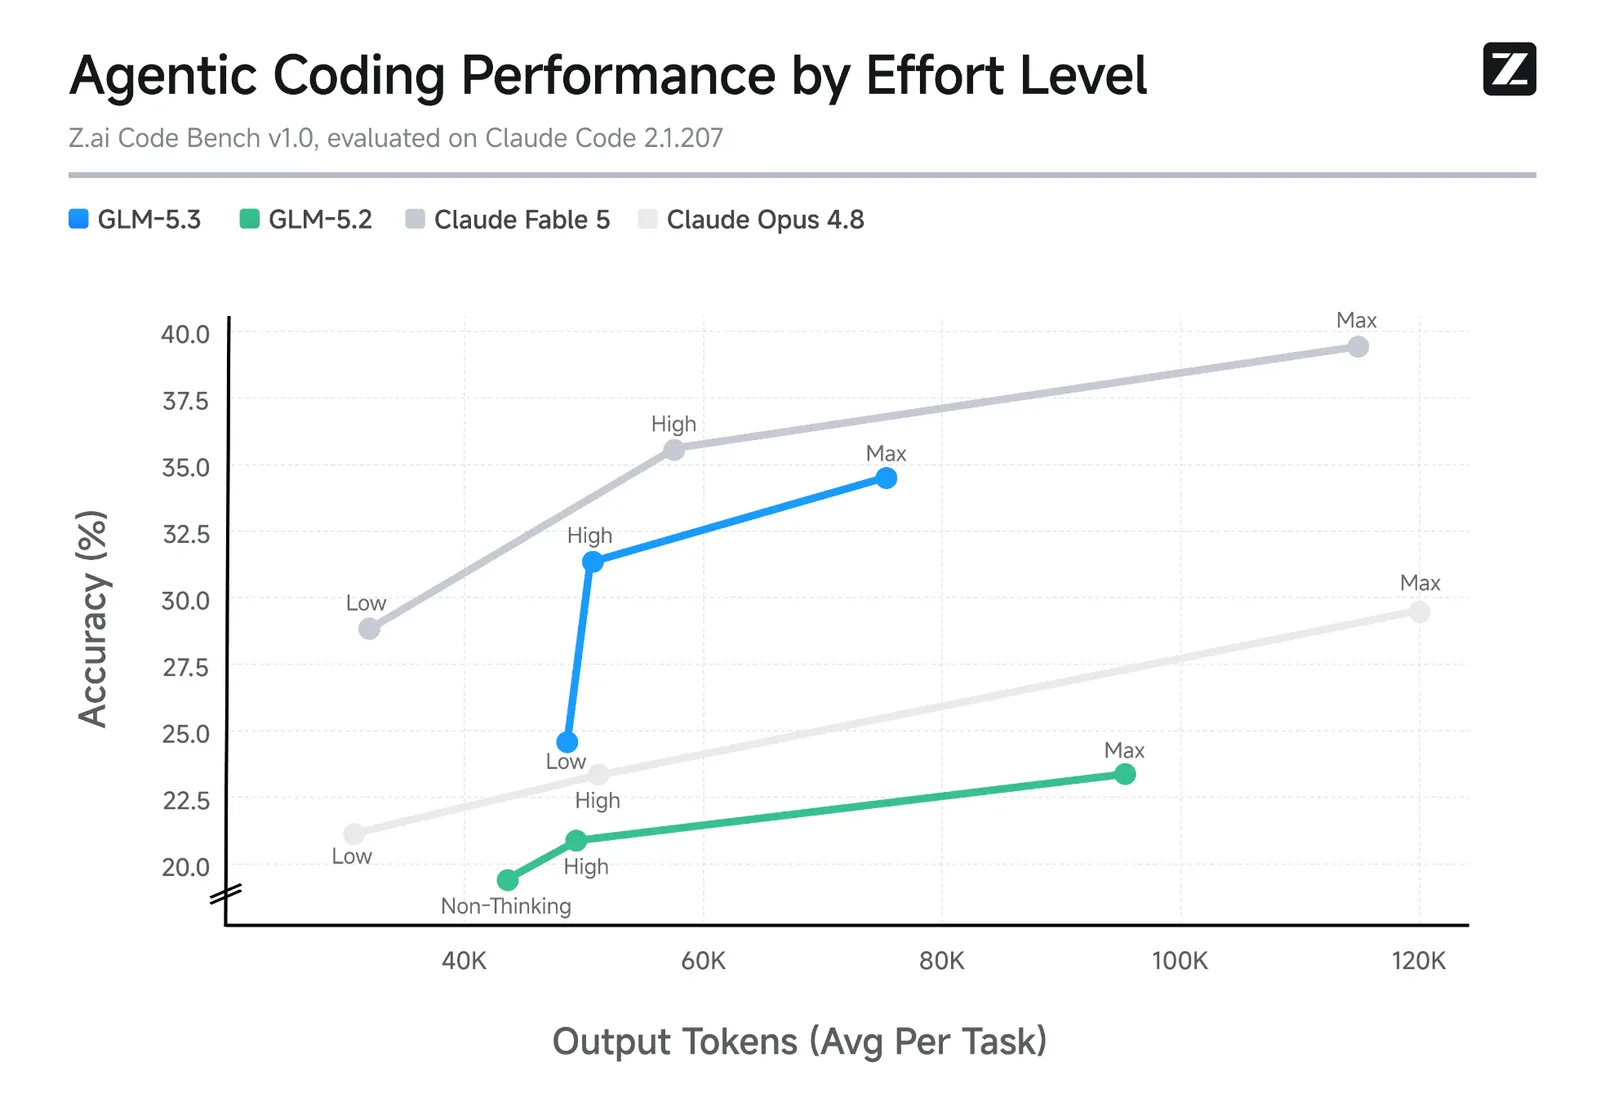 Z.ai's in-house coding benchmark. GLM 5.3 at max effort beats Opus 4.8 at max with fewer tokens, and still trails Fable 5.
I respect that Z.ai published a chart where Claude still wins. Fable 5 sits above GLM 5.3 at every effort level. For my personal agents, GLM 5.3 is plenty.
The weights are open on Hugging Face, so I did look at running GLM 5.3 on the Mac Studio. The model card lists 753 billion parameters. Even squeezed to 4 bits, that's roughly 375GB of weights, about three times the memory in my machine.
Should you trust GLM 5.3 with client data?
Keep anything sensitive away from it. Z.ai is the Chinese company formerly known as Zhipu AI, and I work on the assumption that the Chinese government could see what I send. If you handle client data, health data or anything private, that's the one real reason I'd tell you to skip GLM 5.3.
Price is the other thing to watch. In my GLM 5.2 review I wrote that my old plan's price had more than doubled, and Z.ai has changed its plan prices again since. Check the current number before you commit to a year.
How I'd sign up for GLM 5.3 today
Subscribe to the GLM Coding Plan directly with Z.ai and use their API. Lite lists at $18 a month, Pro at $80 and Max at $168, with 20% off quarterly and 30% off yearly. I'm on Pro, the middle tier. Every plan includes GLM 5.3.
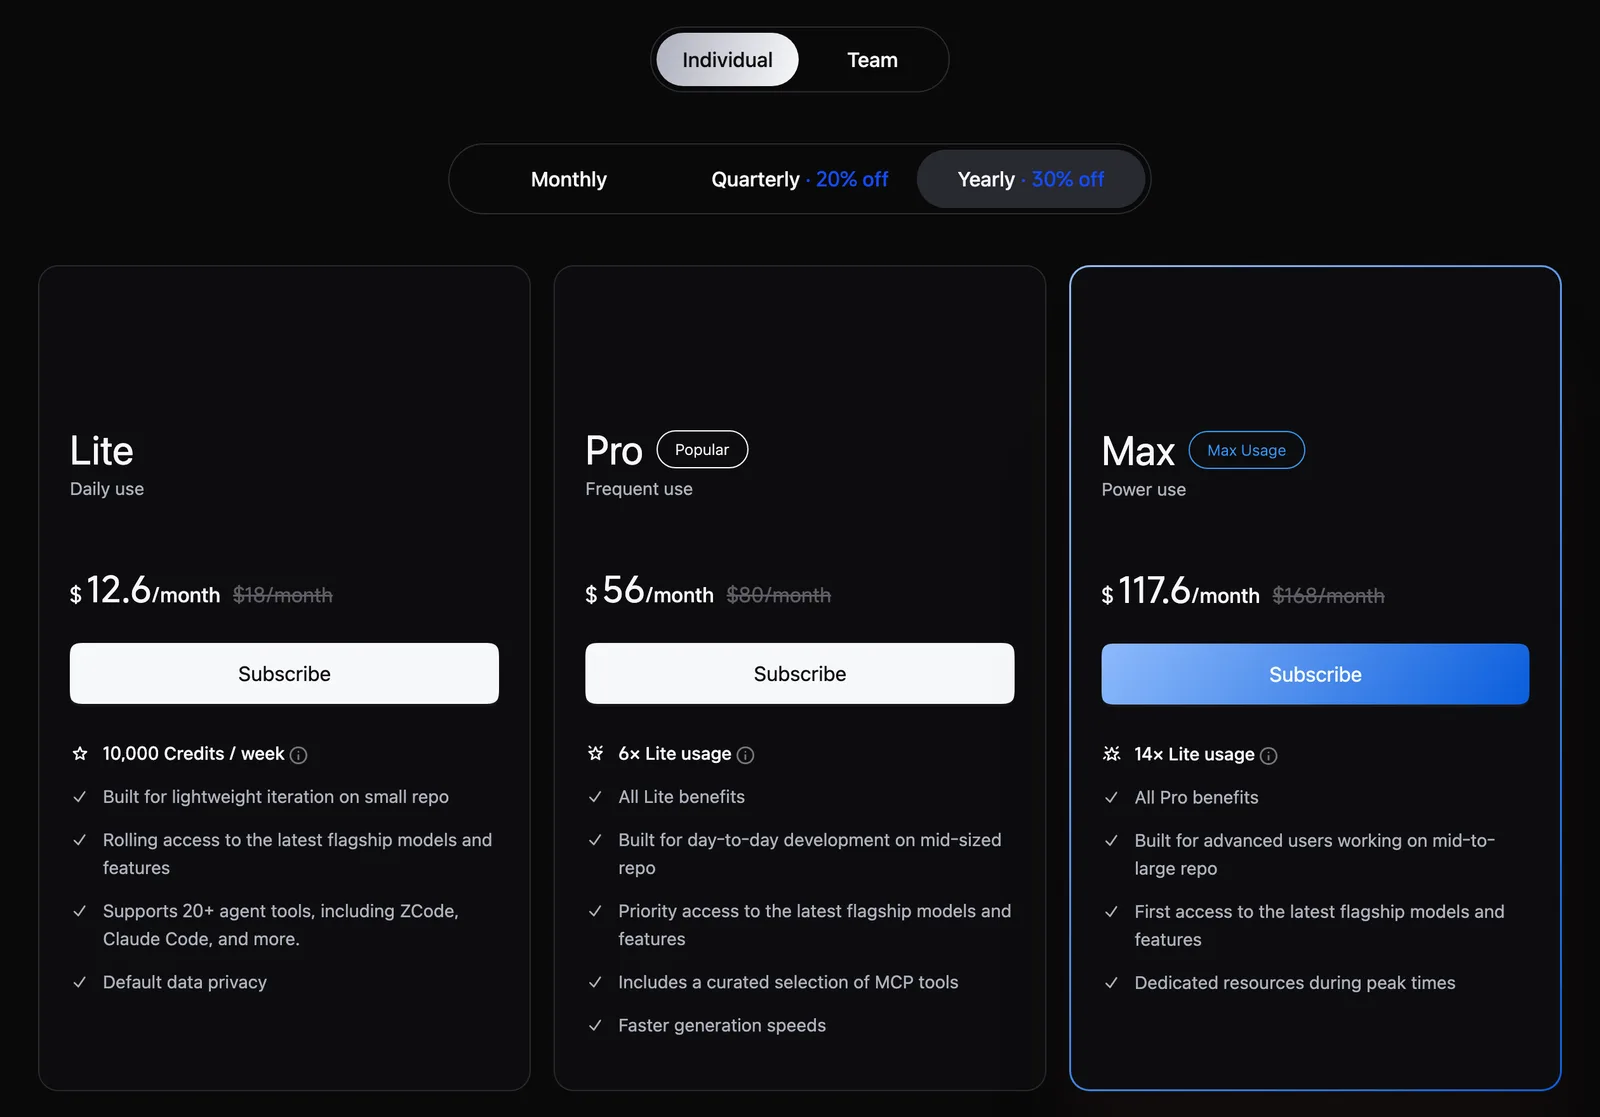 The GLM Coding Plan page with yearly billing selected. Monthly list prices are $18, $80 and $168.
I've changed my mind since my GLM 5.2 review, where I recommended routing through OpenRouter to dodge Z.ai's outages. Z.ai has fixed its uptime since then. The coding plan is a Z.ai subscription, so going direct is now the simplest way to use what you're paying for.
The plan works with Claude Code, OpenCode, Openclaw, Cline and a long list of other agent tools. It also bundles Z.ai's MCP servers for vision, web search, web reading and Zread, so your agent has tools on day one.
If you've been fighting local models to run an agent, try GLM 5.3 on the Z.ai coding plan (referral link) for a month before you buy more hardware. I wish I had.
And if you've gotten Qwen or Nemotron to run a real agent without making things up, I want to know how. Tell me on LinkedIn.
More Notes
 AI Tools
How to Setup a Google Ads MCP Server (and 5 real lessons I learned)
Google Ads is one of the last ad platforms with no managed MCP server. Here is how to build your own locally or on Cloud Run, and the five things that broke on me first.
 AI Tools
Why I Run Some AI Locally and Some in the Cloud
Linux is free as long as you don't value your time. The same is true of local AI. Here is the calculation I run before handing anything to a model, and why I keep local models around anyway.
 AI Tools
Which AI Model Actually Makes Sense for Running a Business
In my experience, most business owners pay little attention to what model they're running. Instead, they just know "I use ChatGPT" or "I use Claude". But the difference and the nuance between models (even from the same model provider) matters a LOT when you use it to run a business. Here's my two cents.
 AI Tools
Why I Build My Own MCP Servers for Google Ads and LinkedIn
An account can burn three days of budget on a broken ad set and nobody finds out until Monday. So I built my own MCP servers for Google Ads, LinkedIn and Sheets. Here is what actually changed.